Building my own LLM, because why not?
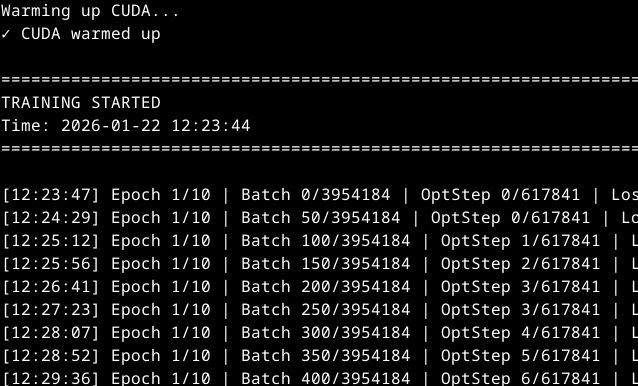
A while back, I decided to train a language model from scratch—not fine-tuning, not LoRA-adapting—but building it all out: initializing weights to noise and building a custom tokenizer from my own corpus. The goal was deeply technical and slightly irrational: I wanted to understand what happens *inside* these models. Not just at the API level, but during those 2 AM moments when the loss curve starts behaving weirdly.
Read more →